How to reduce enterprise ai agent costs through smart orchestration

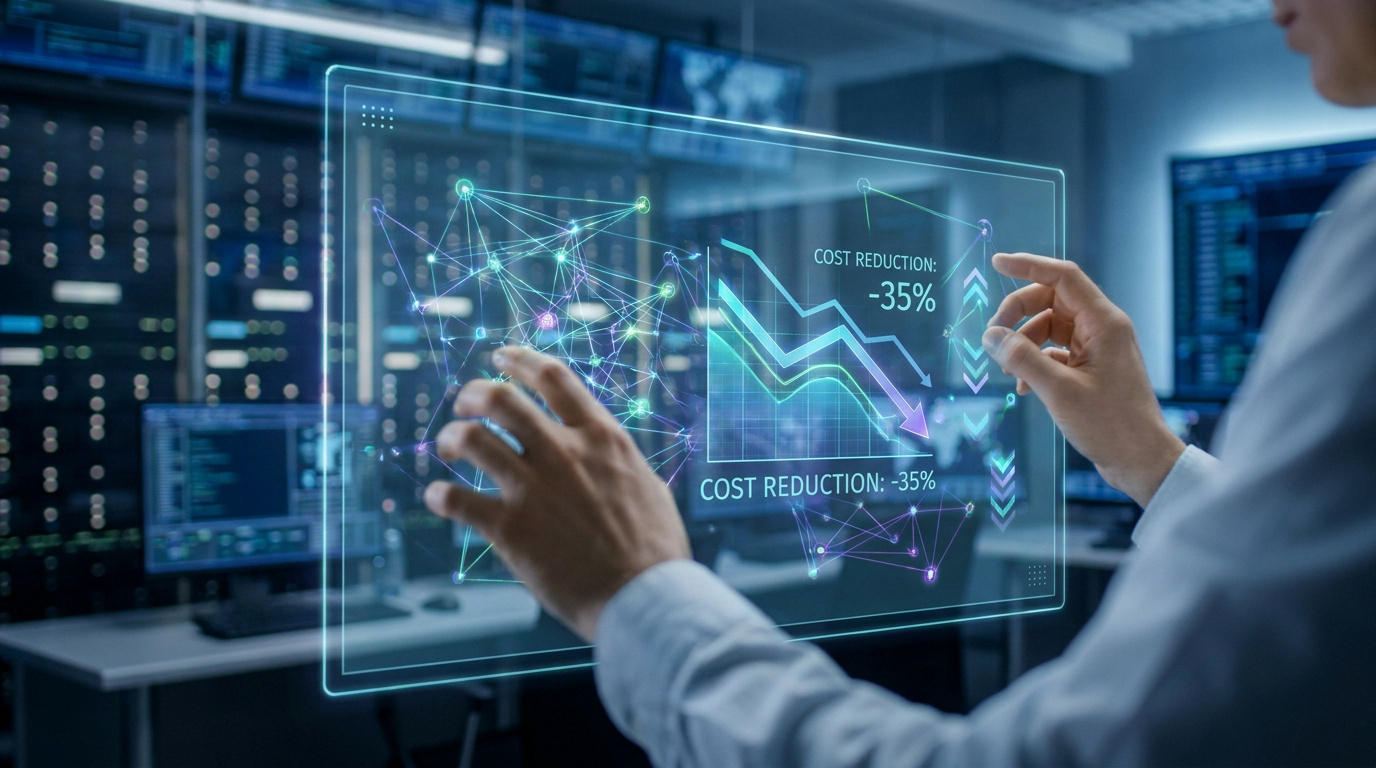
A person using a transparent digital interface to analyze a chart showing a 35% cost reduction for AI agents.
See how smart orchestration can drive a 35% reduction in enterprise AI agent costs.
Key takeaway: Transitioning from token-based billing to cost-per-outcome metrics is essential for sustainable enterprise AI. By deploying intelligent gateways with real-time attribution, automated circuit breakers, and task-specific model routing, organizations can eliminate recursive loop waste. Implementing these governance layers ensures AI expenditures translate directly into measurable business value rather than unmanaged infrastructure overhead.

Enterprise AI costs for a GPT-3.5 equivalent system have dropped significantly, yet unmanaged inference and execution layers often lead to unpredictable budget overruns. Many organizations struggle to maintain fiscal control as autonomous agents trigger recursive loops and high-volume API calls without oversight.

This article outlines enterprise ai agent cost optimization strategies through smart orchestration, moving from raw token metrics to outcome-based efficiency. We analyze model routing, semantic caching, and governance frameworks to transform volatile AI spending into a predictable strategic asset.

  1. Four Layers of AI Stack Expenditure
  2. Deploying Hard Governance via Gateway Orchestration
  3. 3 Dynamic Model Routing and Quantization Tactics
  4. How to Manage Context and Memory for Inference Efficiency?
  5. Strategic Agentic Compilation and Tool Auditing
  6. AI FinOps Versus Traditional Infrastructure Governance

Four Layers of AI Stack Expenditure

Enterprise AI costs in 2026 hinge on four specific layers: inference, infrastructure, agent execution, and overhead. Shifting to cost-per-outcome metrics reveals true efficiency beyond simple token counts, starting with infrastructure fundamentals.

Effective management requires a transition from general orchestration to a precise analysis of technical spending layers.

Breakdown of Inference, Infrastructure, and Operational Costs

The enterprise AI stack comprises four distinct spending layers. These include inference fees and hardware infrastructure requirements. Operational overhead covers essential maintenance and governance tasks.

Agent execution adds complexity. Multiple reasoning loops increase the total cost of ownership. Infrastructure scaling often surprises teams. Budgeting must account for these hidden layers.

Connect these layers to business strategy. Efficiency requires visibility into every tier. This foundation sets the stage for performance tracking.

Shifting From Cost-per-Token to Cost-per-Outcome

Contrast token metrics with business results. Tokens are raw data. Real value comes from completed tasks and successful outcomes.

Outcome-based tracking reflects true agent efficiency. It filters out wasted compute. Success is measured by ROI.
Transitioning to cost-per-outcome metrics allows enterprises to stop subsidizing inefficient prompt engineering and start funding actual business growth through precise agentic performance.

This shift aligns technical spending with corporate goals. Governance becomes the next logical step.

Deploying Hard Governance via Gateway Orchestration

Managing these layers requires strict control at the entry point, starting with how we attribute costs to specific teams.

Real-time Attribution and Departmental Token Budgets

Every agent request must be tagged at the gateway level. Use specific headers to identify business units during each call. This ensures full transparency for every cent spent.

Department Token Limit Priority Level Alert Threshold
Customer Support 50M High 80%
Sales 20M Low 80%
R&D 100M High 80%
Operations 30M Low 80%

Automated budget limits enforce financial discipline. The gateway blocks requests immediately when limits are hit. This prevents unexpected monthly bill shocks for the CFO.

Automated Circuit Breakers for Multi-agent Loops

Circuit breakers are vital in agentic workflows. They stop infinite recursive loops instantly. This protection is necessary for autonomous systems that lose focus during execution.

Budget Risk Warning

Recursive loops in autonomous agents can drain monthly budgets in minutes without circuit breakers.

Triggers are set based on depth or budget. Set a maximum number of turns for each task. Terminate the process if the cost exceeds a threshold. Safety first is the rule.

Deploying Hard Governance via Gateway Orchestration

How to reduce enterprise ai agent costs through smart orchestration involves strict monitoring. Statistics show 40% of enterprise apps will run AI agents by 2026, yet control remains a challenge. Implementing these breakers secures the bottom line.

3 Dynamic Model Routing and Quantization Tactics

Beyond governance, technical optimization through smart routing and model compression offers the most immediate savings. This approach shifts the focus from raw power to surgical efficiency.

Task Classification for Frontier Versus Small Models

Smart orchestration begins with routing simple tasks to lightweight models. Reserve frontier LLMs strictly for complex reasoning. This tiered approach slashes unnecessary high-cost inference significantly.

Criteria for task complexity must be established. Analyze intent and required logic. Use a small “router” model to decide. Automation makes this decision in milliseconds without human intervention.

Efficiency relies on knowing how to reduce enterprise ai agent costs through smart orchestration by avoiding overkill. Lightweight models handle entity extraction perfectly. Frontier models remain the last resort.

Frontier Models

High cost, complex reasoning, high latency. Best for deep analysis.

Small/Quantized Models

Low cost, entity extraction, local deployment, low latency. Best for scale.

Local Deployment via Pruning and Model Quantization

4-bit and 8-bit quantization benefits are substantial. Running these models locally reduces heavy API fees. It also improves data privacy and execution speed.

Reasoning accuracy involves specific trade-offs. Smaller models might lose some nuance. Pruning removes redundant neurons to save memory. Balance is key for production stability.

Selecting the right open-source base is vital. Reviewing options like Kimi K2.5 review helps identify efficient architectures. Local hardware achieves ROI within months.

Fine-tuning Specialized Models to Replace Generalists

Domain-specific training transforms small models. These specialized versions can outperform giants on narrow tasks. This reduces reliance on expensive general-purpose models.

3 Dynamic Model Routing and Quantization Tactics

Fine-tuning yields long-term savings. Initial training costs are high. But, per-request costs drop significantly over time. It is a strategic investment for scale.

Benefits of Fine-tuned Models
  • Lower latency for real-time applications
  • Reduced token usage per request
  • Higher accuracy on niche enterprise data
  • Independence from provider updates

How to Manage Context and Memory for Inference Efficiency?

Efficiently handling the model’s memory is just as vital as choosing the right model size for cost control.

Prompt Caching and KV Cache Prefill Setup

Context management involves using prompt caching and KV cache optimization to avoid recomputing identical input prefixes, significantly lowering prefill costs. This is a technical necessity for agents. The prefill phase calculates intermediate states for all tokens simultaneously.

Detail the setup for static instructions. Cache system prompts across multiple turns. This prevents paying for the same tokens repeatedly. It leverages GPU parallelization during the initial pass to store keys and values efficiently.

How to Manage Context and Memory for Inference Efficiency?

Effective orchestration ensures that standard RAG architectures evolve toward specialized memory handling. This reduces latency during the sequential decoding phase. Every cached token minimizes redundant matrix operations.

Semantic Caching for Redundant API Requests

Describe using vector databases for caching. Store previous agent responses for similar queries. Retrieve them instantly without calling the LLM. This converts the request into a numerical embedding for comparison.

Implementation Tip

Use Redis or vector databases to store previous agent responses for identical queries to bypass LLM calls entirely.

Explain semantic similarity thresholds. Define how “close” a query must be to reuse a result. This prevents unnecessary model invocations. It saves time and money. Accuracy remains high by using cosine similarity measures.

Semantic caching transforms the LLM from a costly reasoning engine into a searchable knowledge base for recurring enterprise queries.

Conversation Truncation and Prompt Compression

Outline strategies for summarizing long histories. Keep token counts within efficient windows. Summarization reduces the burden on the model’s context. It prevents the linear growth of the KV cache from consuming GPU memory.

Mention the CROP technique for efficiency. Balance reasoning quality with token output length. Compress prompts to remove fluff. Every saved token is a saved cent. Techniques like pruning and quantization further reduce computational requirements.

Understanding usage limits and pricing models is essential when managing long-form context. Proper truncation ensures agents stay within quota. Smart orchestration maintains performance while controlling the total token spend.

Strategic Agentic Compilation and Tool Auditing

Optimizing the logic of how agents interact with tools is the final frontier in preventing budget explosions.

Transitioning From Dynamic Loops to Deterministic Blueprints

The ‘Rerun Crisis’ plagues autonomous agents. They frequently repeat identical steps without necessity. This recursive loop drains expensive resources without adding any tangible business value.

Strategic Agentic Compilation and Tool Auditing

Adopt ‘compile-and-execute’ patterns for stability. Convert dynamic reasoning chains into fixed code paths. This ensures predictable execution every time. It effectively eliminates the inherent randomness of raw LLM loops.

Standardizing these workflows prevents the AI wrapper economy pitfalls. Reliable blueprints stabilize operational overhead. Logic replaces pure probabilistic guessing.

Managing Compounding Costs of External Tool Integrations

Third-party API calls carry significant financial risks. These integrations often trigger budget explosions. Agents might call external tools too frequently during autonomous reasoning cycles.

Audit access by limiting tool call frequency. Monitor the specific costs of each integration closely. Set hard caps on external spending to prevent runaway billing cycles.

Effective governance requires a structured approach to tool utility:

  • Cost per call analysis.
  • Necessity of real-time data verification.
  • Alternative local tools availability.
  • Frequency caps per session.

Aligning Dev-test Environments With Production Scales

Testing in low-traffic environments is misleading. It often ignores actual production token volume. This oversight leads to massive surprises during the final launch phase.

Build a framework for simulating realistic scale. Use synthetic loads to predict future costs accurately. Account for peak usage periods. Testing must mirror reality to remain useful.

Enterprises must address the critical gap in automated reviews. Scale testing reveals hidden orchestration inefficiencies. Proactive simulation secures long-term ROI.

AI FinOps Versus Traditional Infrastructure Governance

Finally, we must distinguish AI-specific financial operations from general IT governance to maintain long-term sustainability.

Data Sovereignty Impacts on Operational Overhead

In-house data storage costs require rigorous analysis. Compare these fixed expenses to public cloud API consumption. Sovereignty often increases the initial infrastructure bill significantly.

AI FinOps Versus Traditional Infrastructure Governance

Sovereign AI involves heavy hidden expenses. Specialized staff must handle maintenance and security protocols. Power and cooling requirements add to the total overhead. It represents a complex financial trade-off.

Fragmented architectures across sovereign zones can triple integration costs by 2028. Managing these isolated environments demands strategic procurement. Companies must balance resilience against compliance needs, as seen in recent industry shifts regarding resource allocation.

Observability and Tracing for Cost-draining Behaviors

Distributed tracing is vital for autonomous agents. Identify which specific agent consumes excessive resources. This granular visibility is essential to how to reduce enterprise ai agent costs through smart orchestration.

Observability tools provide necessary depth. Pinpoint inefficiencies within multi-agent collaboration flows. Fix logic bottlenecks that drain the operational budget. Data-driven decisions remain the only viable path forward.

Key metrics for AI FinOps
  • Latency vs Cost
  • Tokens per successful outcome
  • Agent idle time
  • Cache hit ratio
Strategy Primary Benefit
Model Routing Lower cost per token
Caching Reduced API redundancy
Quota Management Predictable budgeting

Smart orchestration transforms unpredictable AI spending into a strategic asset through model routing, semantic caching, and granular governance. Implementing automated circuit breakers and departmental budgets ensures sustainable scaling. Mastering enterprise AI agent cost optimization strategies secures long-term ROI by aligning technical execution with precise business outcomes.

FAQ

How can enterprises categorize AI stack expenditures effectively?

Enterprise AI costs are structured across four primary layers: inference fees, hardware infrastructure, agent execution, and operational overhead. Inference typically accounts for 80% of the budget, representing a recurring operational expense that scales directly with user engagement and token volume.

Infrastructure costs involve the selection of GPUs and cloud services, while agent execution adds complexity through multi-step reasoning loops. Operational overhead includes specialized staffing for maintenance, security, and data sovereignty requirements, forming the total cost of ownership for AI systems.

What is the difference between cost-per-token and cost-per-outcome metrics?

Cost-per-token measures the price of raw data units processed by a model, serving as a direct indicator of compute consumption. However, this metric can be misleading if a cheaper model requires excessive tokens to complete a task, potentially increasing the total expenditure without improving quality.

Cost-per-outcome focuses on business value, calculating the expense required to achieve a specific result, such as a resolved support ticket or a qualified lead. Shifting to this metric allows organizations to align technical spending with actual ROI, filtering out wasted compute and inefficient prompt engineering.

How does smart model routing reduce inference expenses?

Smart routing involves classifying incoming requests by complexity to ensure resource efficiency. Lightweight models handle simple tasks like entity extraction or classification, while high-cost frontier models are reserved exclusively for complex reasoning and deep analysis.

This tiered approach lowers the average cost per token and prevents expensive general-purpose models from being bottlenecked by trivial queries. Automated routers make these decisions in milliseconds, optimizing the balance between performance and expenditure.

What role does caching play in minimizing agentic costs?

Caching strategies, including prompt caching and semantic caching, prevent the redundant recalculation of identical inputs. Prompt caching stores static instructions and system prefixes, significantly reducing prefill costs for long-running agent conversations.

Semantic caching utilizes vector databases to store and retrieve previous agent responses for similar queries. By serving cached results instead of invoking the LLM for every repetitive request, enterprises reduce billable API calls and decrease system latency.

How can automated circuit breakers prevent budget overruns in multi-agent loops?

Automated circuit breakers act as governance tools that terminate recursive loops in autonomous systems. By setting hard limits on the number of turns or the total cost per session, these triggers prevent agents from consuming excessive resources when they lose focus or enter infinite cycles.

These safety mechanisms are deployed at the gateway level to ensure predictable execution. They protect the organization from “bill shocks” by blocking requests once predefined departmental budgets or execution depth thresholds are reached.

What are the benefits of fine-tuning specialized models over using generalist LLMs?

Fine-tuning allows smaller, domain-specific models to match or exceed the performance of large generalist models on narrow tasks. While initial training requires investment, the per-request cost drops significantly due to reduced token usage and lower infrastructure requirements.

  • Lower latency for real-time applications.
  • Reduced token usage through specialized vocabulary.
  • Higher accuracy on niche enterprise data.
  • Independence from third-party provider updates and pricing shifts.

How does model quantization impact local deployment costs?

Quantization techniques, such as 4-bit or 8-bit precision reduction, allow models to run on less powerful hardware with minimal loss in reasoning accuracy. This enables local deployment, which eliminates heavy third-party API fees and enhances data privacy.

By reducing the memory footprint through pruning and quantization, enterprises can maximize GPU utilization. This technical optimization provides immediate savings by decreasing the hardware requirements for maintaining high-performance AI agents.

What metrics are essential for AI FinOps and observability?

AI FinOps requires granular visibility into resource consumption to identify cost-draining behaviors. Distributed tracing identifies which specific agents or departments are resource-heavy, allowing for data-driven optimization of the AI stack.

  • Latency vs Cost: Balancing speed with expenditure.
  • Tokens per successful outcome: Measuring efficiency of task completion.
  • Agent idle time: Identifying underutilized compute resources.
  • Cache hit ratio: Evaluating the effectiveness of caching strategies.

alex morgan
I write about artificial intelligence as it shows up in real life โ€” not in demos or press releases. I focus on how AI changes work, habits, and decision-making once itโ€™s actually used inside tools, teams, and everyday workflows. Most of my reporting looks at second-order effects: what people stop doing, what gets automated quietly, and how responsibility shifts when software starts making decisions for us.